Checking MCMC samples with ArviZ
Sampling the posterior with the No-U-Turn Sampler (NUTS) ends with a distribution of threshold contours, samples we drew from the posterior. Here we show you how to check whether the samples represent the posterior, and which sampler argument to change when they do not.
ArviZ is an established
library for diagnosing Bayesian models.
covariance_to_arviz hands a
psyphy fit to it in the shape it expects, so every ArviZ function works on our samples with no
reshaping. ArviZ and the code call these draws, as in the draw dimension and n_draws.
We say samples. The figure below carries two of the core diagnostics and is a teaser of what this tutorial builds towards.
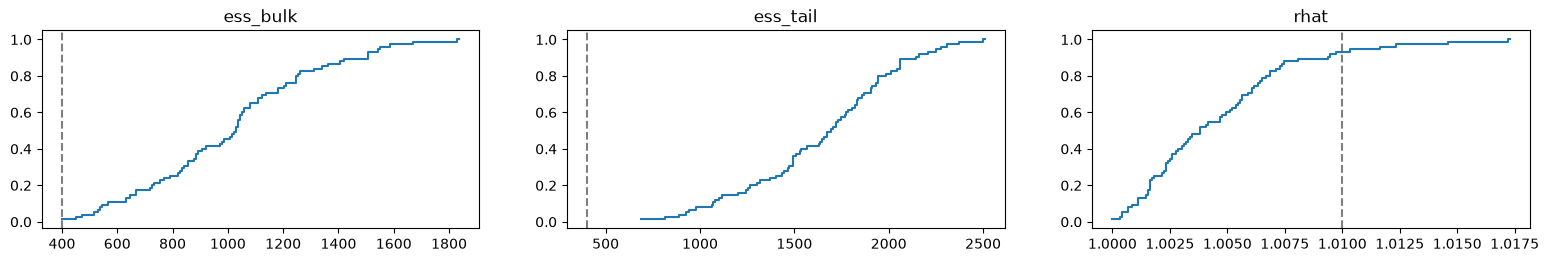
The summary check for posterior samples with ArviZ: Bulk effective sample size (ESS), tail ESS and R-hat, one panel each, over every quantity at every reference point. Dashed lines are ArviZ's reference thresholds, in total ESS across all chains. We want both ESS curves entirely right of their line and the R-hat curve entirely left of its.
Everything here runs on the fit from the
sampling tutorial, from the same script,
nuts_inference_example.py.
You can rebuild every diagnostic and figure from the cached samples without a GPU (a laptop
CPU is fine), like this:
What to check
4 quantities to check. The R-hat and ESS thresholds are ArviZ's defaults, which follow Vehtari et al. (2021). The divergence and tree-depth guidance comes from Stan, a probabilistic programming language for Bayesian models whose MCMC advice is the usual reference, in its reference manual: a divergence is a validity problem (e.g. step size too large), tree-depth saturation only an efficiency one (e.g., whether we need to increase tree-depth).
| check | what it detects | suspect when |
|---|---|---|
divergences, sampler_stats["diverging"] |
the integrator failed, usually in a region of high curvature | any divergence at all |
| R-hat | chains have not mixed to the same distribution | \(\hat{R} > 1.01\) |
| Effective Sample Size (ESS) | autocorrelation: how many independent samples the chain is worth | bulk or tail ESS \(< 100\) per chain, so \(< 400\) in total across 4 chains |
sampler_stats["n_steps"] |
trajectories truncated at the tree-depth cap | at the cap for most samples |
BlackJAX flags a divergence on every sample it takes.
NUTSSampler keeps those flags in
sampler_stats, a plain dict of JAX arrays:
A divergent transition means the integrator, the thing approximating the trajectory in small steps (sampling tutorial), left the posterior's geometry. More sampling doesn't fix the samples it produced.
Any divergence makes the run suspect
One is enough, regardless of what R-hat says, which is why we check divergences first.
The second print is the fraction of samples whose trajectory hit
max_num_doublings: a large fraction means the cap is limiting mixing.
Diagnostics on \(\Sigma\), with covariance_to_arviz
Diagnostics run on \(\Sigma\), not on the raw parameters, for the reason we discussed in the sampling tutorial. One call hands the fit to ArviZ:
az.summary gives one row per quantity: two log variances and one correlation at each of
the 25 reference points we chose, (75 rows total). We see the print output from above for the --mode full
run below:
If you'd like to see all 75 rows instead, just drop the .describe():
| Every quantity, one row each | |
|---|---|
covariance_to_arviz takes the
posterior and the points to evaluate \(\Sigma\) at, here the reference points. From there
az.summary, az.rhat, az.ess and every ArviZ plotting function work on a psyphy fit
directly, which is where the two figures below come from.
Hand it the posterior, not samples from it
posterior.sample(n) flattens (n_chains, n_draws, ...) into one axis, so a sample no
longer carries the chain it came from. R-hat compares the spread between chains against
the spread within them, so once the chains are gone it comes back near 1.00 however
badly they disagreed. ESS is inflated the same way, since shuffling removes the
autocorrelation it measures.
Interpreting the figures
Both figures below are one ArviZ call each, az.plot_trace and
az.plot_convergence_dist, on the object covariance_to_arviz returned. (We write no additional
plotting code here.)
covariance_to_arviz summarizes each \(2\times2\) \(\Sigma\) by the three numbers that
determine it: log_var_0 and log_var_1, the log variances along each axis, and
corr_0_1, their correlation. A trace plot shows how each of those moved over the run. If
the chains converged, they should overlap, stay level, and vary fast from sample to sample.
| Trace plot at the worst reference point | |
|---|---|
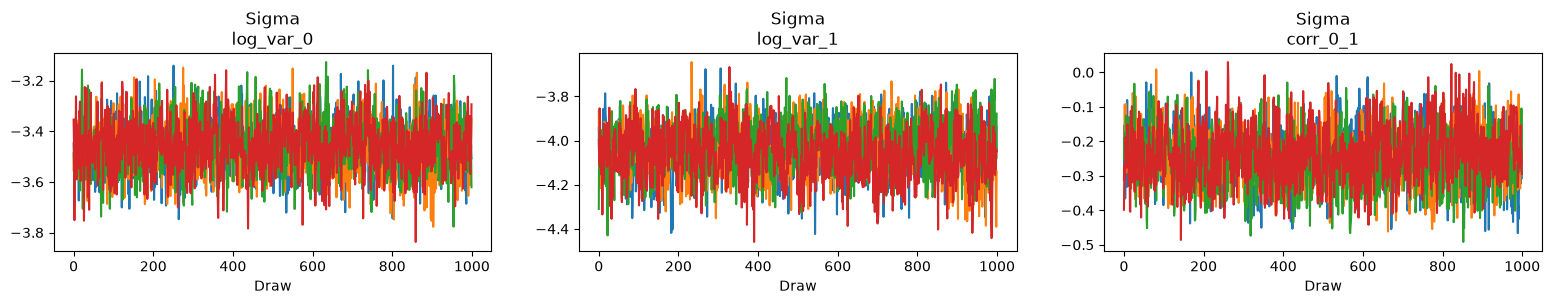
✓ Chains mixed. One panel per quantity at the reference point with the worst R-hat, one colored line per chain. Horizontal axis is the sample index, which ArviZ labels `Draw`. Vertical axis is the value of that quantity.
For comparison, below we show the trace plot of the same reference point from a run that did not converge:
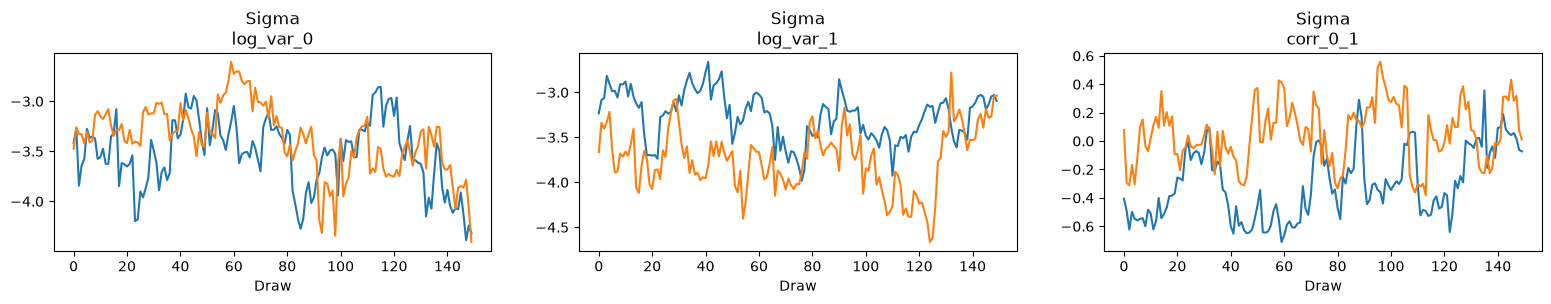
✗ Chains not mixed. The same plot from `--mode quick`: 2 chains, 150 samples.
Read each panel along the horizontal axis:
| in the trace | interpretation | where to see it |
|---|---|---|
| chains overlap, each level, values varying fast from sample to sample | ✓ mixed | the --mode full figure |
| one chain holds its own level | ✗ not mixed | corr_0_1 in --mode quick, the two chains apart for stretches of 40 samples or more |
| a slope at either end | ✗ still drifting, so not mixed | |
| slow swings instead of fast variation | ✗ autocorrelated, so few independent samples | all three --mode quick panels |
A trace plot catches those. It does not catch chains that look fine and still carry too few independent samples, which is what ESS and R-hat are for.
We see one reference point here. The figure at the top covers all 25 at once.
| ESS and R-hat over all quantities | |
|---|---|
The figure from the top of this page, from the code above. The summary check for posterior samples with ArviZ: Bulk effective sample size (ESS), tail ESS and R-hat, one panel each, over every quantity at every reference point. Dashed lines are ArviZ's reference thresholds, in total ESS across all chains. We want both ESS curves entirely right of their line and the R-hat curve entirely left of its.
Each curve there is the distribution of one diagnostic over every \(\Sigma\) quantity at
every reference point, so a point on it reads as "this fraction of quantities scored at most
this value". More is better for ESS and less is better for R-hat. For R-hat: where its
curve crosses the dashed line, that fraction of quantities sits above 1.01. Here a small
fraction does, which is the 1.017 the summary reported.
What to change when a check fails
A failing check is fixed by the sampler arguments, which
blackjax.nuts
and
window_adaptation
document.
| argument | what it controls | psyphy default | raise it when |
|---|---|---|---|
num_warmup |
tuning steps per chain, discarded | 500 | trace plots still drift at the start |
num_samples |
kept samples per chain | 1000 | ESS is too low |
num_chains |
independent chains, R-hat needs at least 2 | 4 | a stronger convergence check is wanted |
max_num_doublings |
tree-depth cap, at most \(2^k - 1\) gradients per sample | 8, against BlackJAX's 10 | most samples hit the cap, which the script prints |
target_acceptance_rate |
how cautious the tuned step size is | 0.8 | divergences appear |
Compute presets
The presets scale three separate things: how much data there is, how accurately the
likelihood is estimated (mc_samples), and how long the sampler runs. The first two
change the posterior being targeted, so a quick fit is a smaller problem rather than a
rough version of a full one.
Compute costs of a run
- The Monte Carlo likelihood dominates. Each gradient evaluation simulates
mc_samplesnoisy internal representations for every trial, so cost scales withmc_samples * n_trials.quicktofullraises that product by about 440 times. - Cost per sample varies. NUTS needs \(O(2^{\text{tree depth}})\) gradient evaluations and the depth is data dependent, commonly 16 to 64.
- Tree depth is capped. The default
max_num_doublings=8allows at most \(2^8 - 1\) gradient evaluations per sample. Ifsampler_stats["n_steps"]sits at the cap for most samples, trajectories are being truncated: still valid, but mixing more slowly. - Warmup starts from a prior-scaled metric. By default the sampler works in
\(z = W / \sigma_\text{prior}\) (
prior_preconditioning=True), so adaptation does not begin from an identity mass matrix mismatched to the coefficient scales. - Chains are vmapped. All chains advance in one compiled call per phase. Under vmap each step costs as much as the deepest tree across chains (which is another reason for the depth cap). On a GPU four chains cost about as much as one. On a CPU, many chains can be slower than running them one at a time.
What step_size does
step_size picks between two code paths. The paths are BlackJAX's, but the choice is
psyphy's: BlackJAX has no notion of modes, and NUTSSampler dispatches on whether this
argument is None.
step_size |
what happens | call |
|---|---|---|
None (default) |
window_adaptation tunes the step size and mass matrix per chain, starting from a prior-scaled metric |
NUTSSampler(num_warmup=200, num_samples=500) |
| a float | no adaptation and an identity mass matrix. Warmup becomes plain burn-in, so it is faster, and the step size has to be chosen by hand | NUTSSampler(..., step_size=0.01) |
psyphy deviates in two places from the BlackJax defaults:
prior_preconditioning=True samples \(z = W / \sigma_\text{prior}\) and maps the samples
back to \(W\), so adaptation starts from a metric matched to the prior scales. And
max_num_doublings defaults to 8 here (against BlackJAX's own 10).
Further reading
- API reference:
covariance_to_arviz,NUTSSampler,MCMCPosterior - The fit these diagnostics run on: Sampling the posterior with NUTS.
- Why the diagnostics take \(\Sigma\) and the posterior object, and which
sample_statskeys a new sampler has to spell ArviZ's way: developer notes. - ArviZ for the diagnostics, with its getting started guide and the arviz-stats API
- BlackJAX for the sampler and its arguments
- Stan's reference manual for
divergences and tree depth, including the reparameterization route when raising
target_acceptance_rateis not enough
The paper behind the ArviZ thresholds:
Vehtari, A., Gelman, A., Simpson, D., Carpenter, B., & Bürkner, P.-C. (2021). Rank-normalization, folding, and localization: an improved \(\widehat{R}\) for assessing convergence of MCMC. Bayesian Analysis, 16(2). doi:10.1214/20-BA1221